What data observability actually means for Salesforce
Observability is a term borrowed from software engineering. In that world, it means instrumenting your systems, so you always know what's happening inside them. Not just when something breaks, but continuously.
For Salesforce, it means the same thing applied to your data: knowing how your fields are populated, how that's changing over time, and what the health of your data looks like on any given day, not just after someone complains.
It's the difference between a smoke alarm and a fire investigation. One tells you something is wrong before it spreads. The other starts after the damage is done.
Why good Salesforce data doesn't stay good
Data health is not a fixed state. It degrades continuously.
Every day, records get created, updated, and imported. Integrations push data in ways no one fully audited. Sales reps fill fields inconsistently. Someone renames a field, and a downstream process quietly breaks. A required field gets bypassed through an API import, and nobody notices.
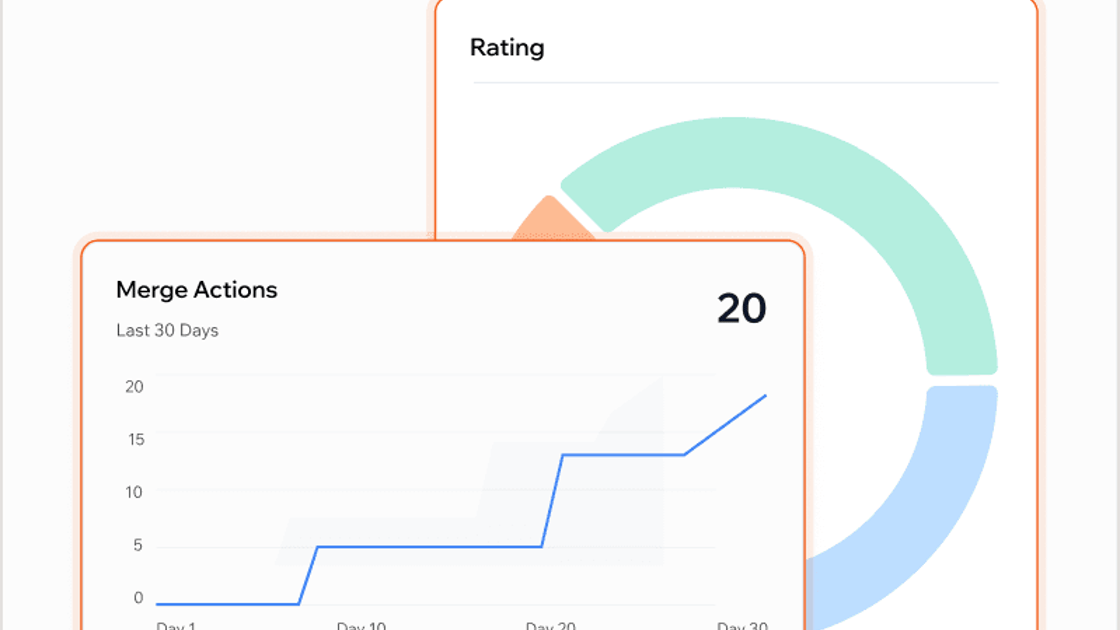
A field that was 95% populated last quarter may be sitting at 60% today. Nothing flagged it. No alert fired. The field still exists, the records still exist, and every automation or report that depends on it is now running on something unreliable.
This is the normal state of a Salesforce org. Not because admins aren't doing their jobs, but because data quality is a moving target, and most orgs have no way of watching it move.
Why the annual cleanup can't catch this
The standard response to data quality problems is some version of a periodic audit: export the data, find the issues, clean them up, and schedule the next one for six months from now.
The problem is that an audit is a snapshot of a moving target.
By the time you run the next one, you've already had months of drift. Automations have already skipped records. Reports have already produced numbers nobody trusts. And if you're rolling out AI agents or Agentforce, those agents have already been operating on fields you haven't checked since last quarter.
The audit isn't wrong. It just isn't enough on its own. What's missing isn't a better cleanup; it's the habit of watching in between.
What it looks like to watch instead of react
Take two signals every admin knows: fill rate and duplicates.
Fill rate drop, found late: A contact email field that feeds an enrollment automation quietly drops from 88% to 61% over eight weeks. Nobody notices until the campaign team reports a 30% drop in delivery. The admin investigates, traces it back to an integration change that wasn't accounted for, and fixes it. Three weeks of bad sends, one frustrated marketing team, and an awkward conversation with leadership.
Fill rate drop, caught early: The same scenario, but this time there's a scheduled analysis job running weekly. By week three, the trend is already visible: fill rate is moving the wrong way. The admin investigates before anyone downstream feels it, fixes the integration, and the campaign runs cleanly.
Same problem. Completely different outcome, because one org was watching and one wasn't.
The same principle applies to duplicates. A duplicate rate that creeps up over a quarter isn't just a data quality issue. It's an AI readiness issue. If an AI agent is working off contact records and two of them represent the same person, it will treat them as different people. It has no way to know otherwise. It will use what's there.