Skip to content

The Power Automate dedupe flow that always breaks, and what it actually costs you per project

  • Dynamics 365
  • Deduplication
  • Automation
Power Automate Dedupe Flow Cost. Photo by Microsoft 365 on Unsplash

You built the flow. It worked. Then it didn't.

Native duplicate detection wasn't catching records coming in through the integration, so you built a Power Automate flow to fill the gap: trigger on record creation, retrieve potential matches, compare field values, flag or merge on a match. Straightforward, done in an afternoon.

It worked fine in testing, and fine for the first two weeks after go-live. Then a schema change came through, or the client added a custom entity, or the flow hit a throttling limit during a bulk sync and silently stopped processing. By the time anyone noticed, three weeks of undetected duplicates were sitting in the environment.

This is one of the most common workarounds in the Dynamics 365 CE consultant's toolkit, and one of the most reliably fragile. Not because Power Automate is a bad tool, but because deduplication isn't the problem it was built to solve.

Why consultants reach for Power Automate

Power Automate is already in the stack. It needs no additional licensing, no deployment pipeline, no IT approval. A consultant who knows the platform can build a working deduplication flow in a few hours, which is an easy yes for a client who needs something running before go-live.

It also looks good in a demo: the trigger fires, the record gets checked, the duplicate gets flagged. The client sees the logic, understands it, signs off. What happens six months later, when the flow breaks in a way nobody sees in the interface, is a problem for future-you.

How the flow breaks, and why it's hard to catch

Power Automate deduplication flows break in characteristically quiet ways. The flow doesn't throw an error the client will notice. It just stops doing what it was supposed to do.

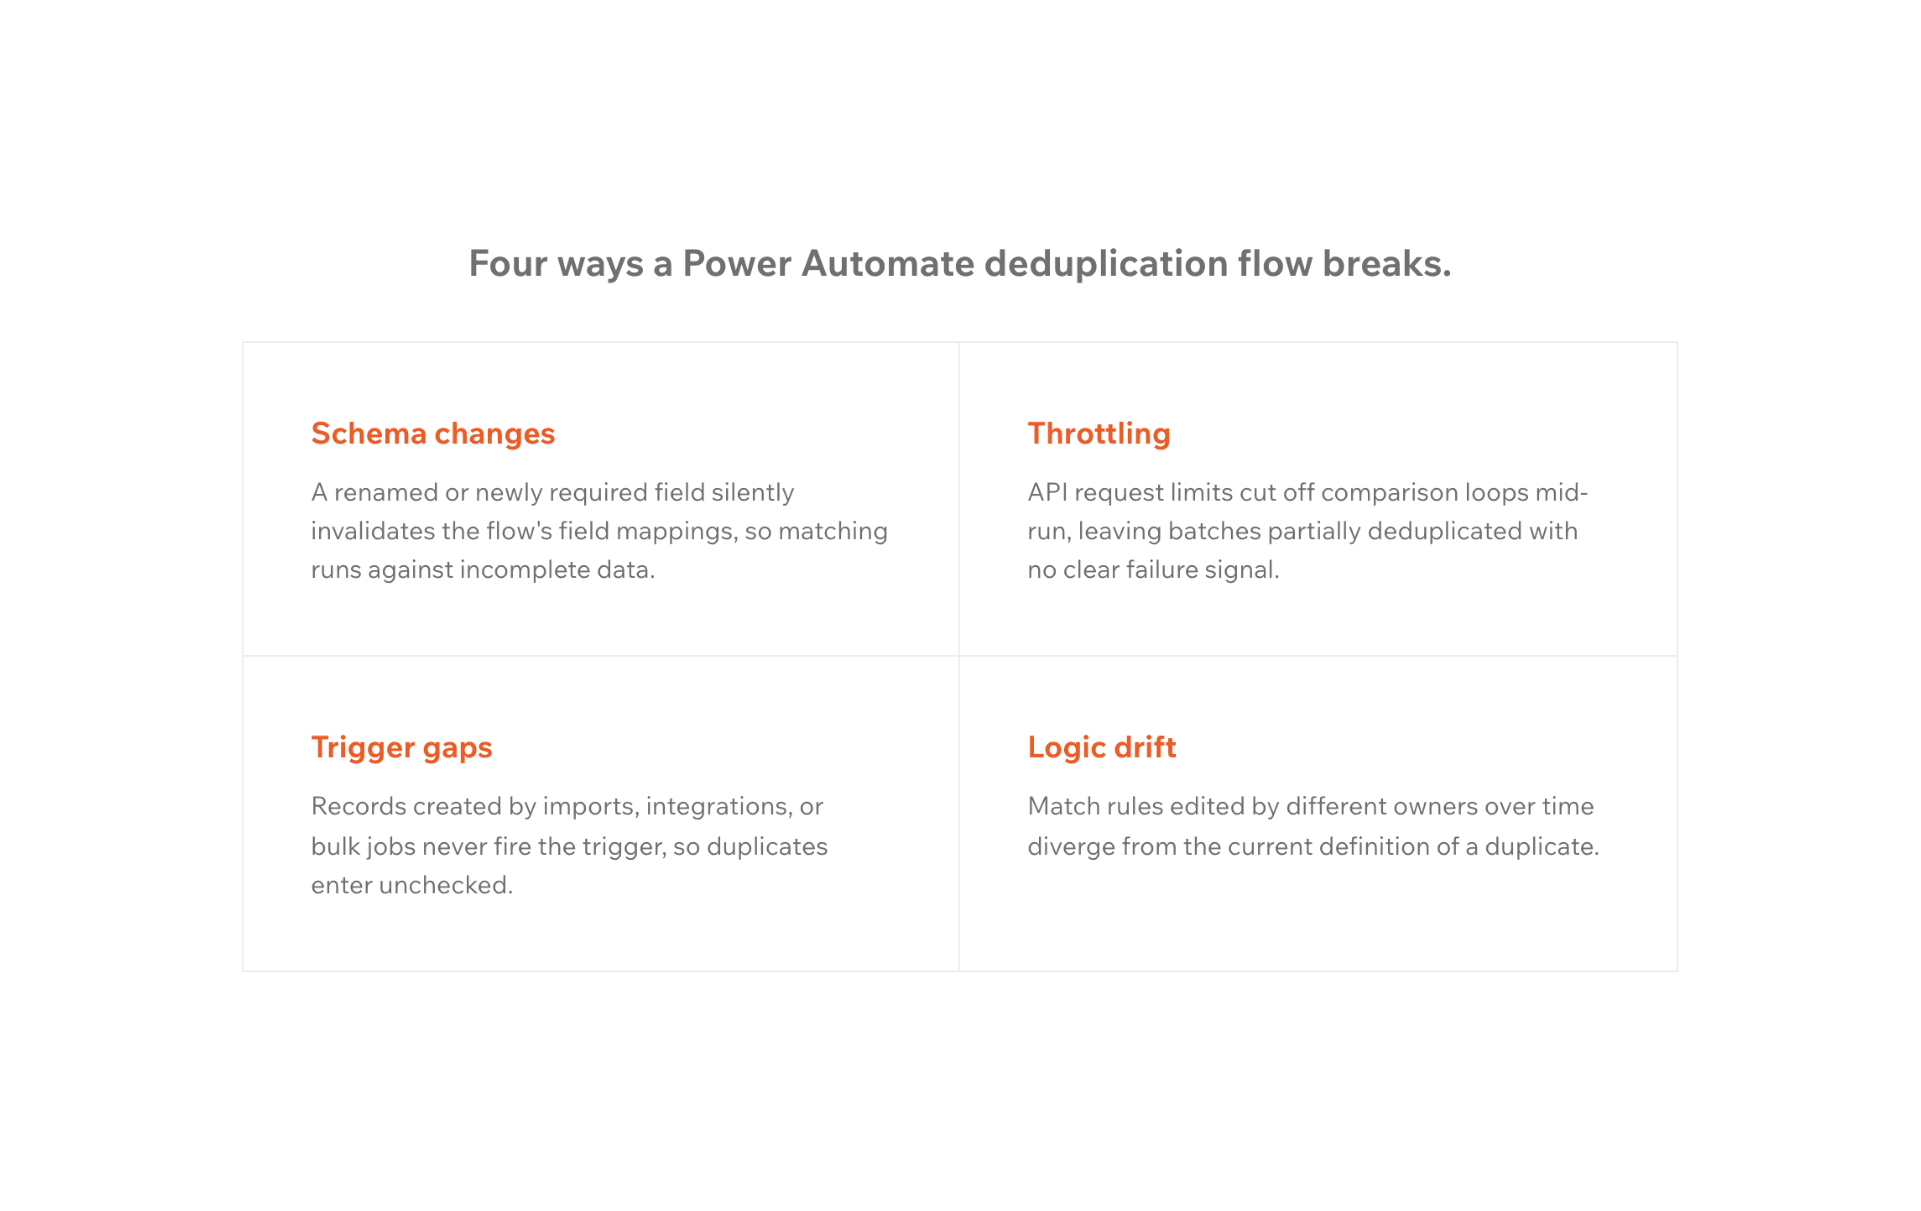
  • Schema changes. The flow references specific fields on the entity. When the client's team adds or renames a field, which happens routinely in the first few months post-go-live, the flow either breaks silently or starts comparing the wrong values. Nobody gets an alert, and duplicates accumulate.
  • Throttling during bulk operations. Power Automate has API call limits. During a bulk import, a large integration sync, or a migration from a connected system, the flow gets throttled. Records arrive faster than it can process them. The ones that don't get checked are exactly the ones most likely to be duplicates, because bulk operations usually bring in data from external systems where the problem is worst.
  • Trigger gaps. The flow triggers on record creation through the UI or specific connectors. Records arriving via the Web API, Dual-Write, or a connector that wasn't configured when the flow was built don't trigger it. The flow is running; it's just not running on the records that matter most.
  • Logic drift. Matching logic that made sense at the start of the project, match on email, or on company name plus phone, starts producing false positives as the data model evolves. Someone adjusts the logic, the adjustment introduces a new edge case, and the flow starts merging records it shouldn't or missing ones it should catch. Nobody notices until a client calls about a missing contact.
  • Maintenance dependency. The flow was built by the consultant who knew the data model at project time. When that consultant moves to a different engagement, the institutional knowledge goes with them, and the next person who has to debug the flow is working from a black box.
Four ways a Power Automate deduplication flow breaks.

What a broken flow actually costs per project

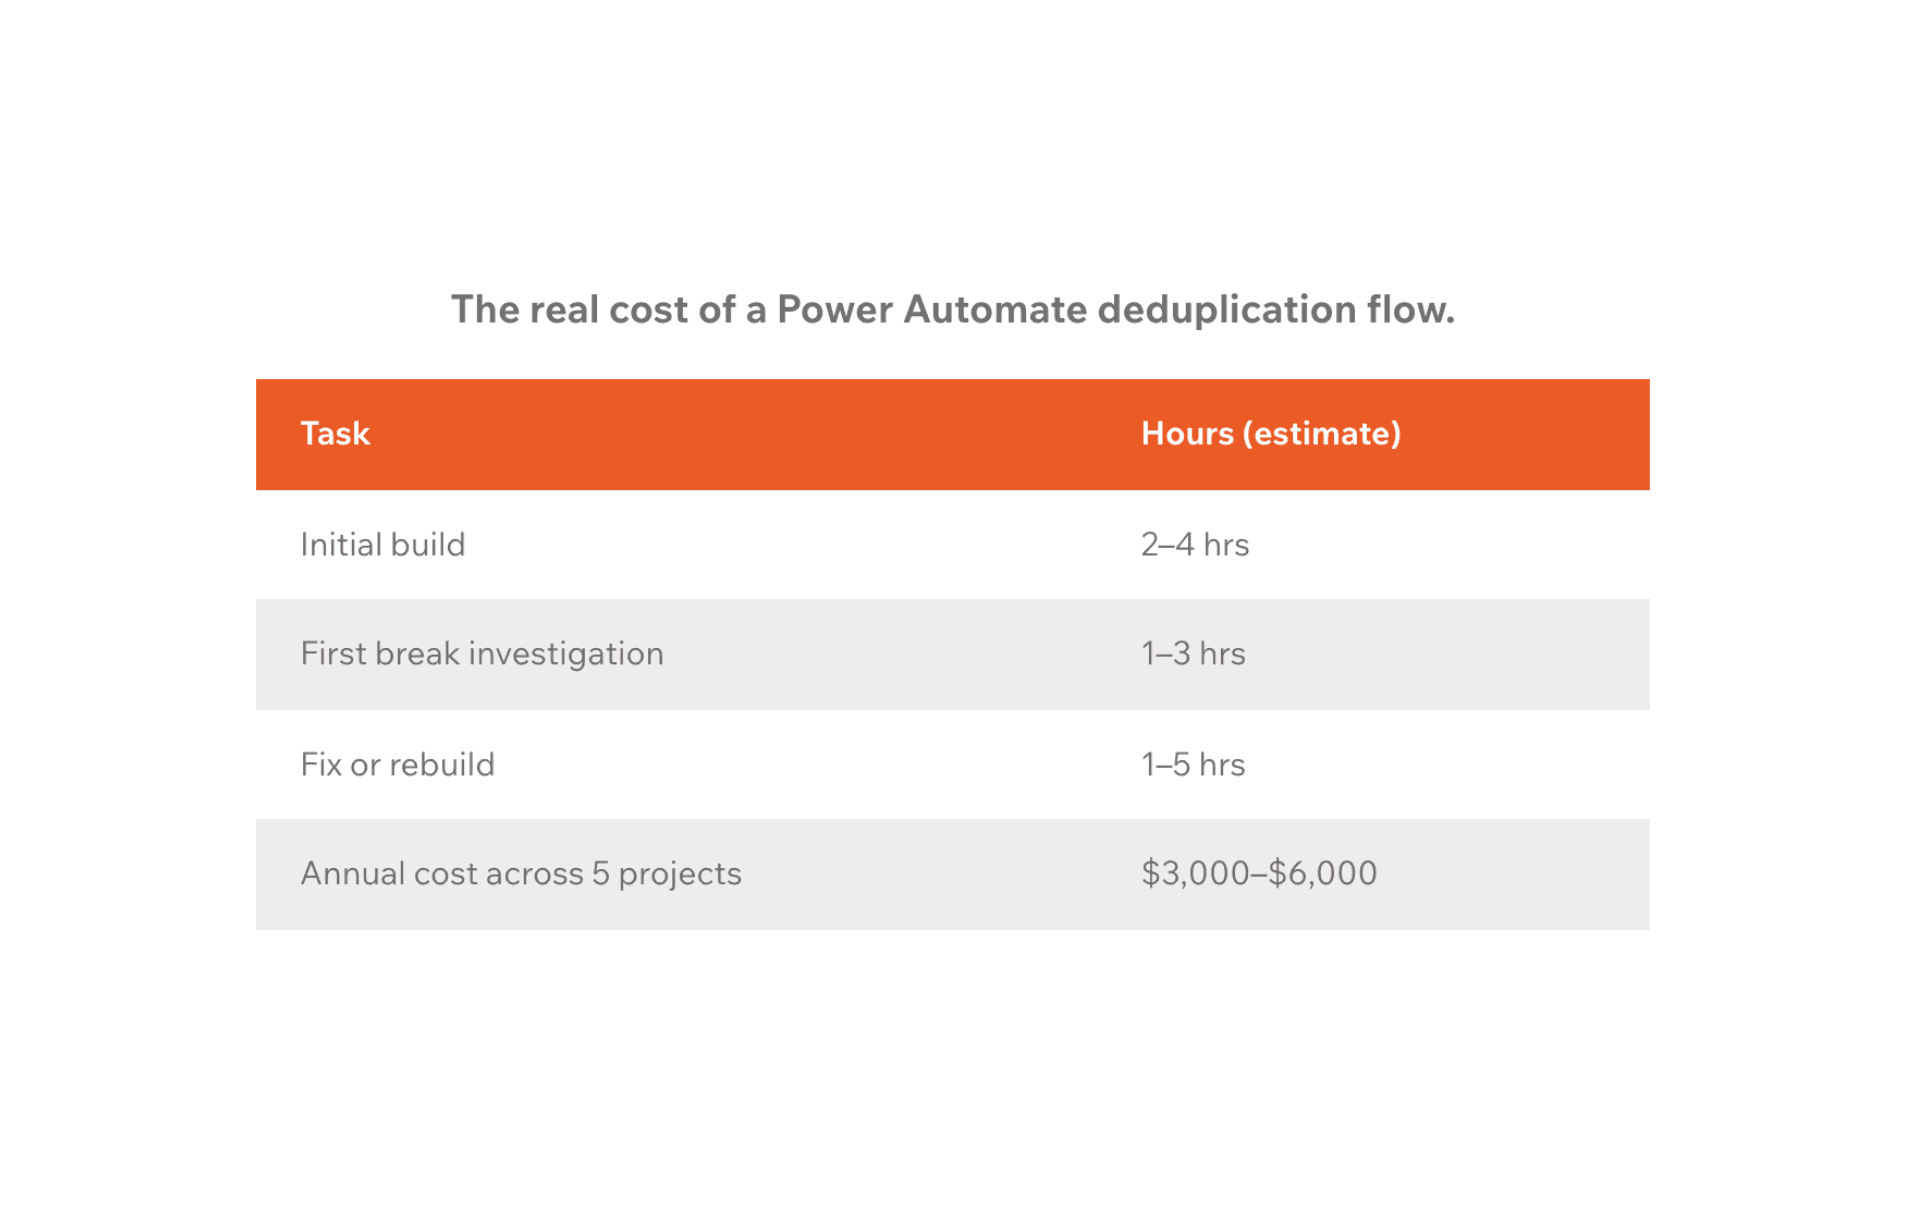
The direct build cost is low: two to four hours of a consultant's time to build and test a basic deduplication flow. That's the number that goes in the project estimate, and it's roughly accurate for the initial build.

Everything after that is where the cost accumulates, and where it stops showing up on timesheets.

  • First break investigation. One to three hours to find where the logic broke, trace it back to a schema change or a throttling event, and decide whether to fix or rebuild.
  • Fix or rebuild. A fix takes one to two hours; a rebuild takes three to five. On a project with a complex entity model, a rebuild is the more common outcome.
  • Duplicate cleanup. The records that piled up while the flow was broken still need addressing, a bulk detection job, manual review, or a scripted merge, and each takes time proportional to how long the flow was down before anyone noticed.
  • Repeat. The average Power Automate deduplication flow breaks two to three times in its first year. Each break runs the same investigate-fix-cleanup cycle.

At a conservative billing rate of $100 an hour, a flow that breaks twice in its first year costs $600 to $1,200 in unscoped remediation, on top of the initial build. On a fixed-fee project, that comes out of margin. On time and materials, it's an awkward conversation with the client about why deduplication keeps needing attention.

Across five projects in a year, the remediation cost for Power Automate flows alone runs $3,000 to $6,000, for a workaround chosen specifically because it looked like the cheap option.

The real cost of a Power Automate deduplication flow.

Why Power Automate is the wrong tool for deduplication

Power Automate is a workflow automation platform. It processes events, triggers actions, and moves data between systems, and it does those things well.

Deduplication is a data integrity problem. It needs matching logic that runs at the data layer, coverage across every entry point into Dataverse, and reliability that doesn't depend on trigger configuration, API limits, or which connector happens to be configured. Power Automate wasn't built to provide any of that, and the gaps show up exactly where they hurt: during high-volume operations, after schema changes, and on entry points the flow was never built to cover.

The flow works until data volume grows, the schema changes, or a new integration comes online. On a live Dynamics 365 CE environment, all three happen routinely.

Preventing duplicates inside Dataverse instead

A duplicate-prevention layer that runs inside Dataverse, at the platform level rather than the workflow level, doesn't have trigger gaps, doesn't get throttled during bulk operations, and doesn't break when a field gets renamed. It covers every entry point regardless of how the record arrived, works on standard and custom tables, and doesn't need a consultant to maintain matching logic as the data model evolves.

Plauti installs directly from Microsoft Marketplace and runs entirely within the client's Dataverse environment. Matching rules, merge logic, and field survivorship are configured once at implementation, then apply consistently across every entry point from then on. There's no flow to maintain, no throttling ceiling to manage, and no silent failure mode that lets duplicates pile up before anyone notices.

For the project budget, that turns deduplication into a known, fixed cost at implementation instead of a recurring remediation cost that shows up unpredictably through the project's lifetime.

Before you build the next flow

The next time deduplication comes up on a project, it's worth asking whether the Power Automate flow is the right answer or the familiar one.

If the client's environment is simple, a handful of standard entities, no bulk integrations, minimal ongoing data volume, a well-scoped flow might hold up. But bulk imports, Dual-Write, a custom entity model, or an integration likely to grow will break it. The question is whether to scope that cost upfront or absorb it later.
Hungry for more?

Frequently asked questions

Why does my Power Automate deduplication flow keep breaking in Dynamics 365 CE?

Power Automate deduplication flows typically break because of schema changes that invalidate field references, API throttling during bulk operations that causes records to be skipped, or trigger gaps that leave certain entry points uncovered. These failures are usually silent, so duplicates accumulate before anyone notices the problem.

How much does it cost to maintain a Power Automate deduplication flow in Dynamics 365 CE?

The initial build cost is low, typically two to four hours. The ongoing cost is harder to predict: each break takes one to three hours to diagnose, one to five hours to fix or rebuild, plus additional time for duplicate cleanup. A flow that breaks twice in its first year costs $600 to $1,200 in unscoped remediation at a $100 an hour rate, not counting cleanup work. Across multiple projects, that adds up to a significant recurring cost for a solution chosen because it looked inexpensive.

Does Power Automate work for deduplication in Dynamics 365 CE?

Power Automate can handle basic deduplication under controlled conditions. It becomes unreliable at scale, during bulk imports, large integration syncs, or as the data model evolves post-go-live, and it doesn't cover entry points that weren't configured when the flow was built, including Web API inserts and Dual-Write syncs. For implementations with ongoing data volume or multiple integration entry points, a native Dataverse deduplication layer is more reliable.

What is the alternative to a Power Automate deduplication flow in Dynamics 365 CE?

A duplicate-prevention layer that runs natively inside Dataverse covers every entry point, UI form saves, Web API calls, bulk imports, and integration syncs, without depending on trigger configuration or API throttling. It applies consistent matching and merge logic across standard and custom tables, configured once at implementation rather than maintained per project. For practices running multiple migrations a year, that turns a variable recurring cost into a predictable one-time step.

Deduplication for Microsoft Dynamics 365

Configured once per environment, covering every entry point. See how other CE practices restructured this.